Configuration of a forced aligner. More...
#include <cxx-api.h>
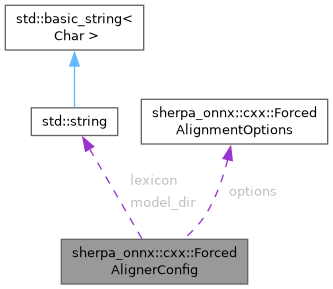
Public Attributes | |
| std::string | model_dir |
| std::string | lexicon |
| ForcedAlignmentOptions | options |
| bool | debug = false |
Detailed Description
Member Data Documentation
◆ debug
| bool sherpa_onnx::cxx::ForcedAlignerConfig::debug = false |
◆ lexicon
| std::string sherpa_onnx::cxx::ForcedAlignerConfig::lexicon |
Path to the pronunciation dictionary used to build the lexicon FST. One pronunciation per line:
key [probability columns ...] phone1 phone2 ...
Probability columns (floating point numbers between the key and the phones, e.g. MFA .dict files) are ignored. Several lines under one key give several pronunciations of the same word/character and ALL are kept: each pronunciation becomes a parallel path in the lexicon FST and the acoustics pick the one used by the alignment. This is how Chinese polyphones avoid text-level guessing.
The key shape depends on the language: English = words, Chinese = hanzi characters/phrases (hanzi-keyed), other languages = their writing units. Multi-word phrases keep their combined readings: a multi-token key writes one " || "-separated phone group per word/character ("银行 || i n || h a ŋ"); single-token keys need no " || " ("行 x a ŋ"). Words without a pronunciation are reported as out-of-vocabulary and aligned as the model's OOV phone.
Word intervals are recovered along the pronunciation path actually taken by the alignment; they are not counted with the phone count of the first pronunciation (pronunciations differ in length).
The lexicon FST is not shipped with the model; it is built at load time in kaldi dictionary form (optional silence + word output symbols).
◆ model_dir
| std::string sherpa_onnx::cxx::ForcedAlignerConfig::model_dir |
Directory of one forced-alignment acoustic model. Required files:
- meta.json: feature chain + silence/OOV parameters (parsed once at construction, field by field)
- final.alimdl: the alignment model (kaldi format: TransitionModel + AmDiagGmm); note it is final.alimdl, NOT final.mdl
- tree: the context dependency tree (ContextDependency)
- lda.mat: required iff the feature chain is splice+LDA
- phones.txt: optional phone table (falls back to the phones list in meta.json when missing)
Other files of the upstream model bundles (final.mdl, phone_lm.fst, graphemes.txt, rules.yaml, ...) are unused and ignored; missing required files are reported by name.
◆ options
| ForcedAlignmentOptions sherpa_onnx::cxx::ForcedAlignerConfig::options |
The documentation for this struct was generated from the following file:
- c-api/cxx-api.h
