Loading...
Searching...
No Matches
sherpa_onnx::cxx::GenerationConfig Struct Reference
Generation-time options for advanced TTS synthesis. More...
#include <cxx-api.h>
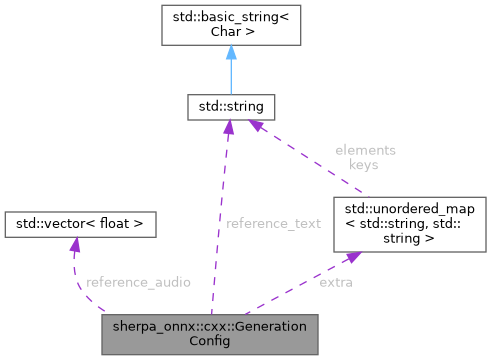
Collaboration diagram for sherpa_onnx::cxx::GenerationConfig:
Public Attributes | |
| float | silence_scale = 0.2 |
| float | speed = 1.0 |
| int32_t | sid = 0 |
| std::vector< float > | reference_audio |
| int32_t | reference_sample_rate = 0 |
| std::string | reference_text |
| int32_t | num_steps = 5 |
| std::unordered_map< std::string, std::string > | extra |
| std::vector< std::vector< int32_t > > | phoneme_codepoints |
| std::vector< std::vector< std::string > > | tokens |
Detailed Description
Member Data Documentation
◆ extra
| std::unordered_map<std::string, std::string> sherpa_onnx::cxx::GenerationConfig::extra |
◆ num_steps
| int32_t sherpa_onnx::cxx::GenerationConfig::num_steps = 5 |
◆ phoneme_codepoints
| std::vector<std::vector<int32_t> > sherpa_onnx::cxx::GenerationConfig::phoneme_codepoints |
Pre-phonemized input as Unicode codepoints.
Phonemize the text yourself (for instance with piper_phonemize) and pass the resulting codepoints here. When set, it is used in place of the text argument. Leave empty to use text with a lexicon.
Each inner vector is one sentence.
◆ reference_audio
| std::vector<float> sherpa_onnx::cxx::GenerationConfig::reference_audio |
◆ reference_sample_rate
| int32_t sherpa_onnx::cxx::GenerationConfig::reference_sample_rate = 0 |
Sample rate of reference_audio.
◆ reference_text
| std::string sherpa_onnx::cxx::GenerationConfig::reference_text |
◆ sid
| int32_t sherpa_onnx::cxx::GenerationConfig::sid = 0 |
◆ silence_scale
| float sherpa_onnx::cxx::GenerationConfig::silence_scale = 0.2 |
◆ speed
| float sherpa_onnx::cxx::GenerationConfig::speed = 1.0 |
◆ tokens
| std::vector<std::vector<std::string> > sherpa_onnx::cxx::GenerationConfig::tokens |
Pre-tokenized input, e.g. Chinese pinyin like "zhong1".
Each inner vector is one sentence.
Mutually exclusive with phoneme_codepoints: if both are set, a warning is printed and generation fails.
The documentation for this struct was generated from the following file:
- c-api/cxx-api.h
